NVIDIA
Metrics, Dashboards, Alerts and more for NVIDIA Integration in Sysdig Monitor.

This integration is enabled by default.
This integration is out-of-the-box, so it doesn’t require any exporter.
This integration has 14 metrics.
List of Alerts
| Alert | Description | Format |
|---|---|---|
| [Nvidia] Gpu Temperature Too High | GPU temperature exceeded the configured threshold. Risk of thermal throttling or hardware damage. | Prometheus |
| [Nvidia] Gpu Memory Exhaustion | GPU VRAM usage exceeded the configured threshold. The device is at risk of out-of-memory errors. | Prometheus |
| [Nvidia] Gpu Underutilization | GPU utilization has been below the configured threshold for too much time. The device may be idle or misconfigured. | Prometheus |
List of Dashboards
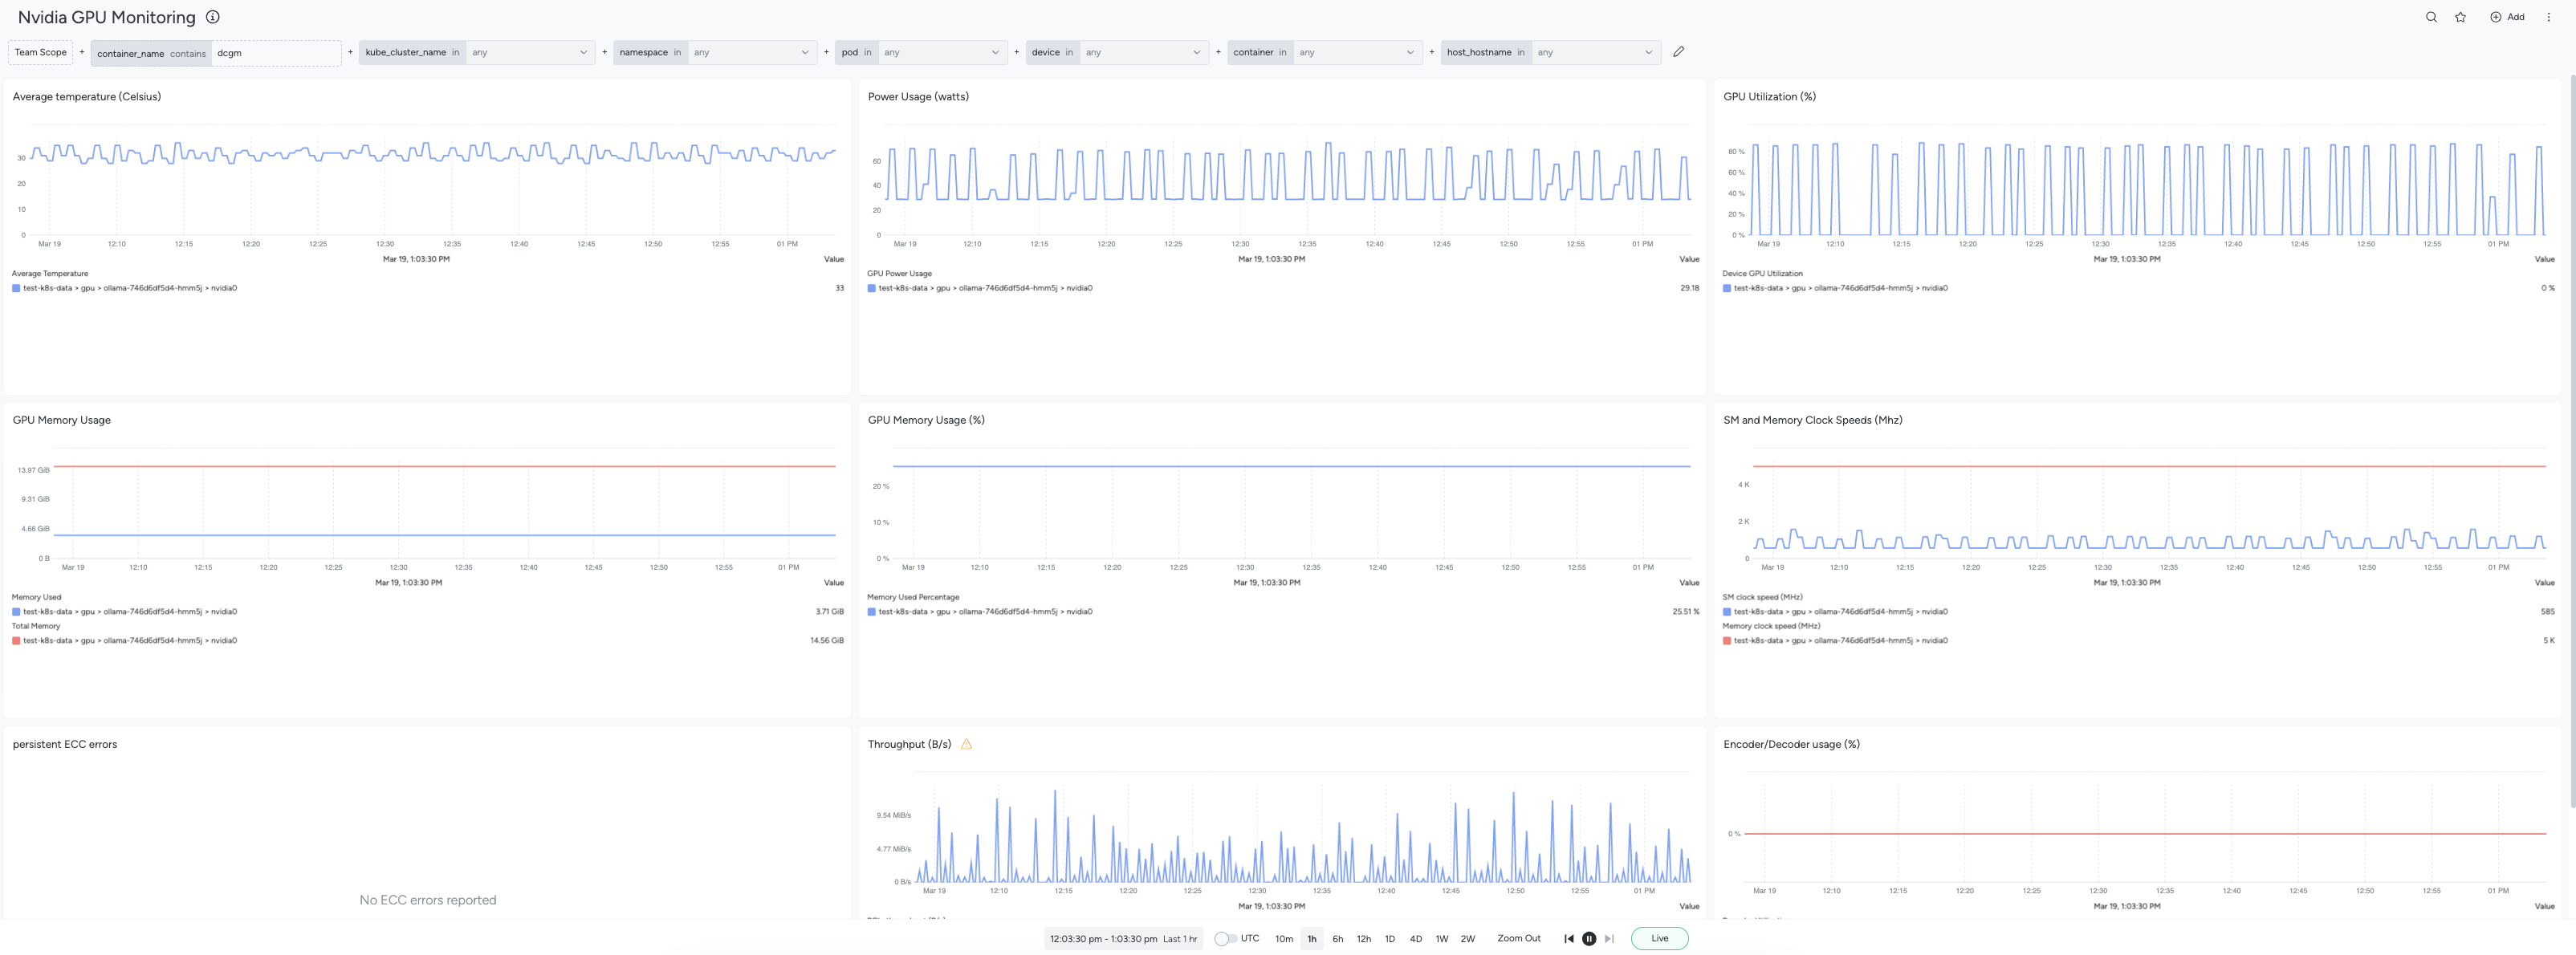
Nvidia GPU Monitoring
The dashboard provides information on the status and usage of NVIDIA GPUs.
List of Metrics
| Metric name |
|---|
| DCGM_FI_DEV_DEC_UTIL |
| DCGM_FI_DEV_ENC_UTIL |
| DCGM_FI_DEV_FB_FREE |
| DCGM_FI_DEV_FB_USED |
| DCGM_FI_DEV_GPU_TEMP |
| DCGM_FI_DEV_GPU_UTIL |
| DCGM_FI_DEV_MEM_CLOCK |
| DCGM_FI_DEV_POWER_USAGE |
| DCGM_FI_DEV_SM_CLOCK |
| DCGM_FI_PROF_NVLINK_RX_BYTES |
| DCGM_FI_PROF_NVLINK_TX_BYTES |
| DCGM_FI_PROF_PCIE_RX_BYTES |
| DCGM_FI_PROF_PCIE_TX_BYTES |
| kube_node_labels |
Prerequisites
None.
Installation
Installing an exporter is not required for this integration.
Agent Configuration
The default agent job for this integration is as follows:
- job_name: nvidia-metrics
  scrape_interval: 30s
  kubernetes_sd_configs:
    - role: pod
  relabel_configs:
    - action: keep
      source_labels: [__meta_kubernetes_pod_host_ip]
      regex: __HOSTIPS__
    - source_labels: [__meta_kubernetes_pod_container_name]
      action: keep
      regex: '.*dcgm-exporter'
    - action: replace
      source_labels: [__meta_kubernetes_pod_uid]
      target_label: sysdig_k8s_pod_uid
    - action: replace
      source_labels: [__meta_kubernetes_pod_container_name]
      target_label: sysdig_k8s_pod_container_name
